Skip to content

Big Data

Oracle Big Data Cloud Service – Compute Edition

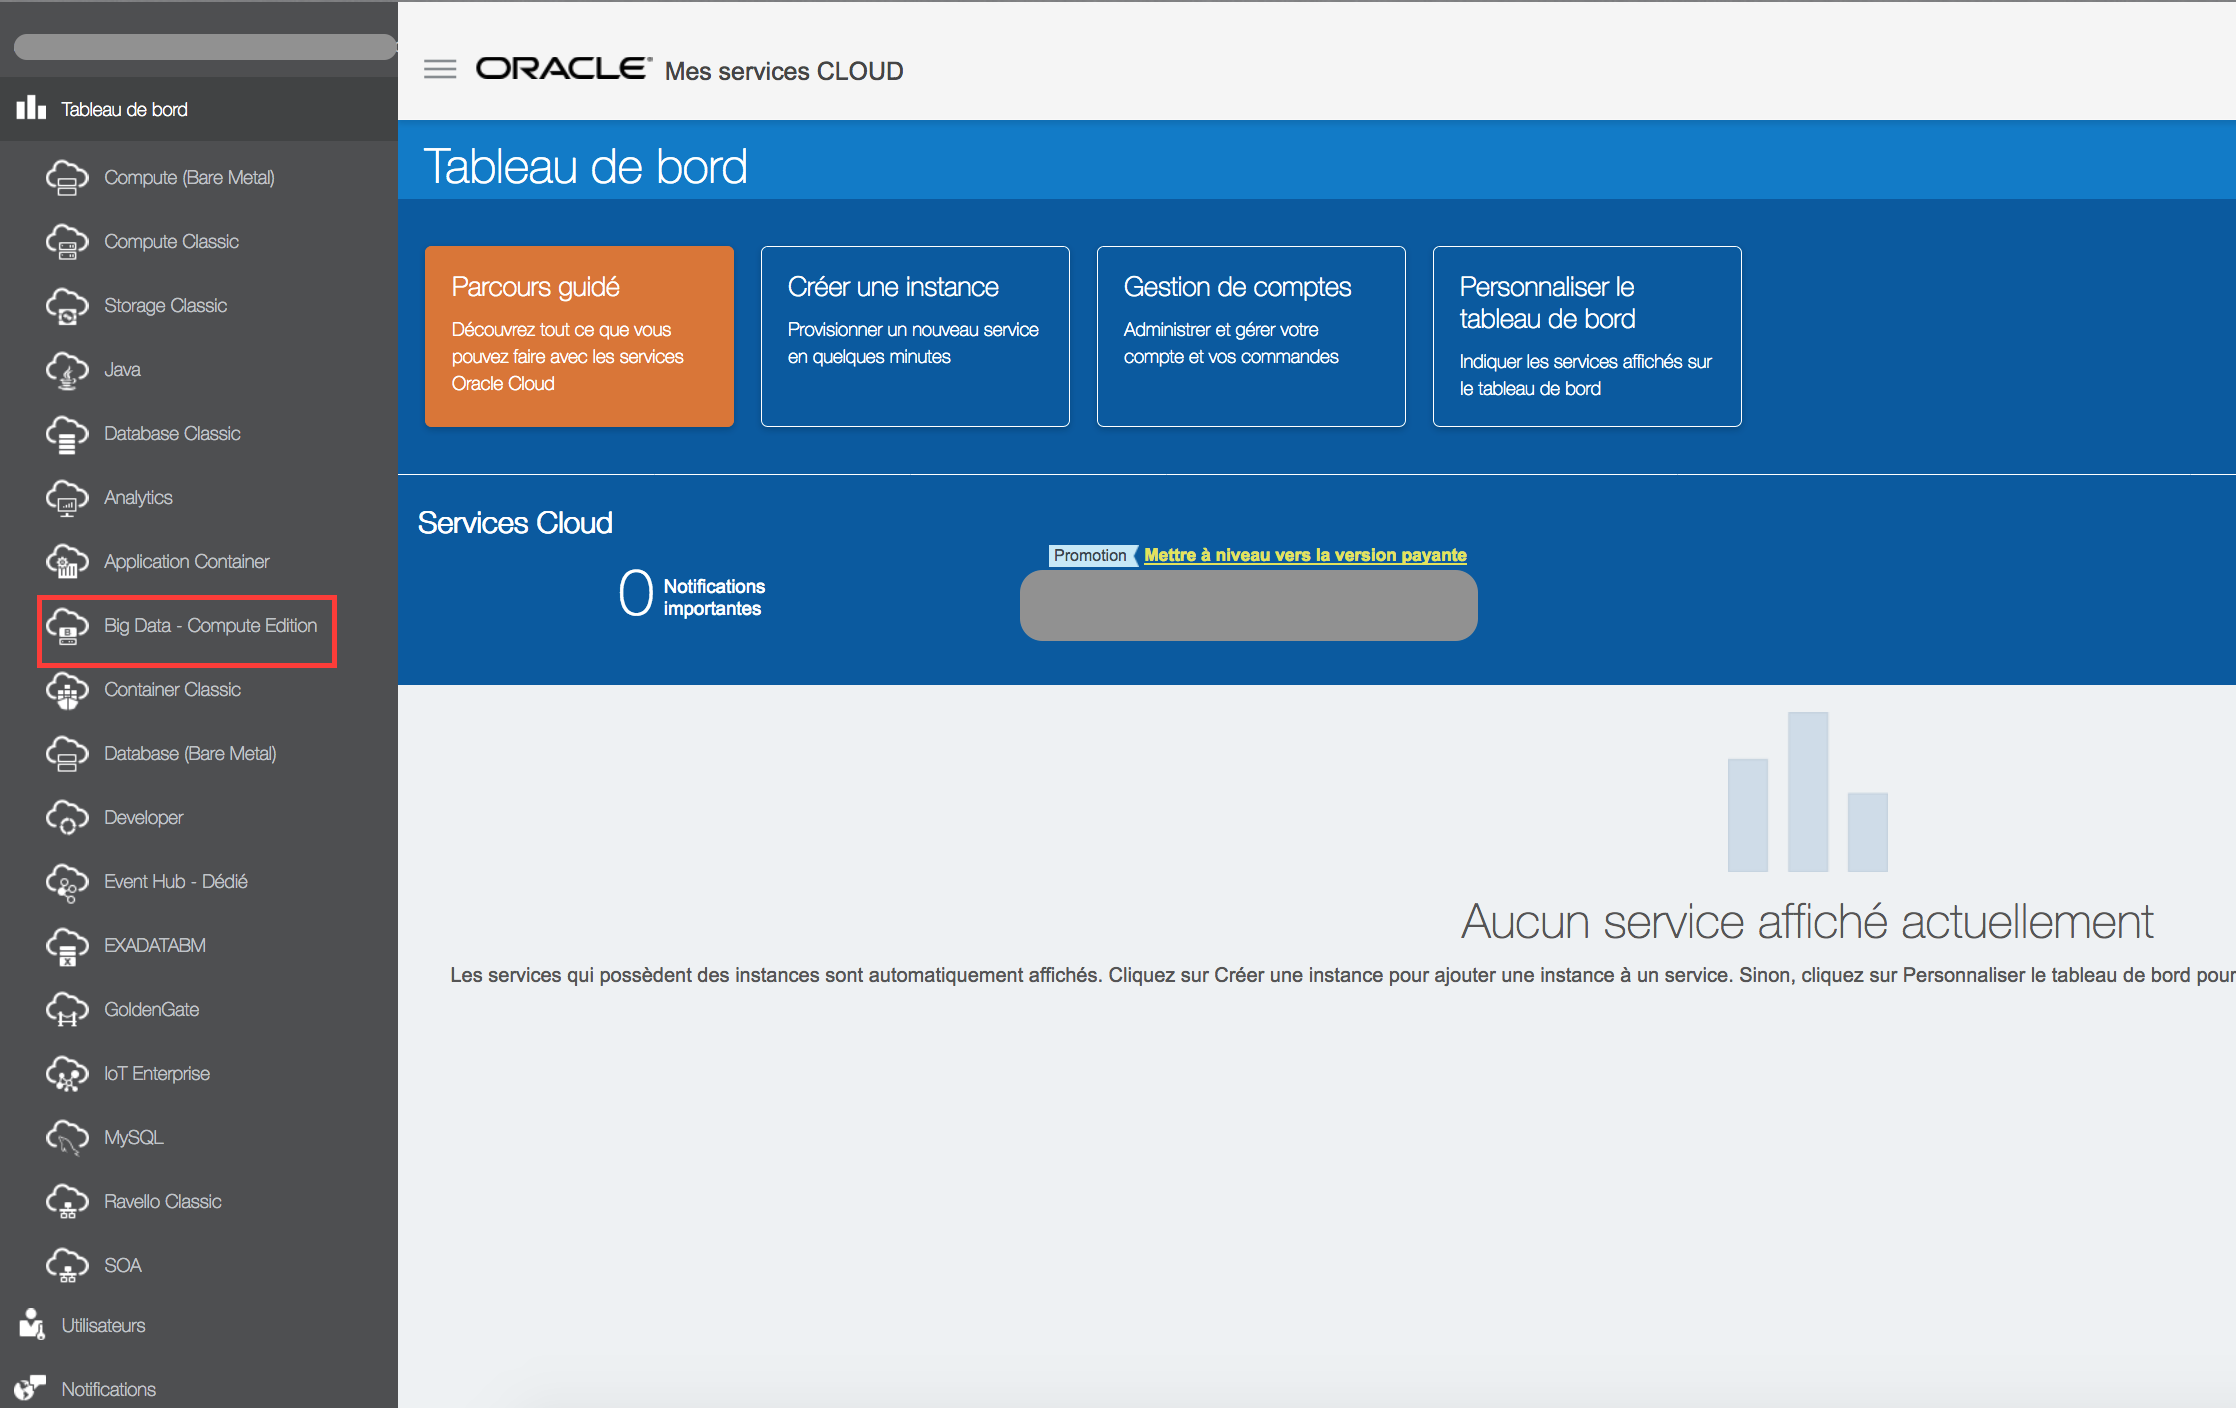
In this blog post, we will see how to create a Big Data cluster through the Oracle Cloud Services. If you want more details about the Oracle Big Data cloud services offering, you can refer to my previous blog Introduction to Oracle Big Data. First, you need to create your trial account through the following link: https://cloud.oracle.com/tryit. Note that, when… 
Install Apache Kafka on Linux

What is Apache Kafka ? No, Kafka is not only the famous author (en.wikipedia.org/wiki/Franz_Kafka), it’s an open-source distributed pub-sub messaging system with powerful skills like scalability and fault tolerance. It’s also a stream processing platform (near real-time) for the streaming datasources. The design of Apache Kafka is strongly influenced by the commit logs. Apache Kafka was originally developed by Linkedin and was… 

Introduction to MongoDB

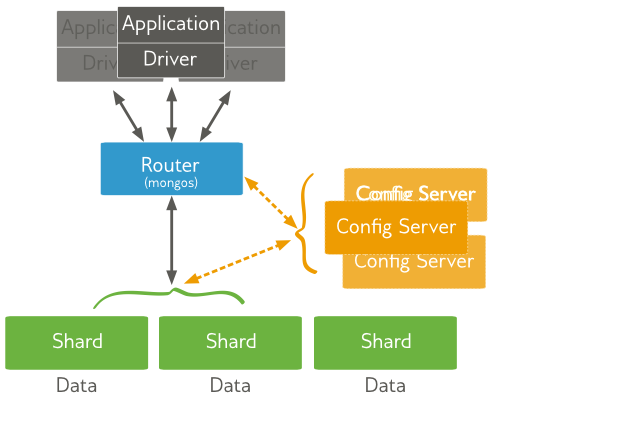
MongoDB is an open source NoSQL database management system document-oriented. MongoDB allows the manipulation of structured and unstructured data. It is schema-less and can be used to store a large data volume. This blog is explaining the main principle of the DBMS. MongoDB stores data in documents. These documents are stored in BSON types, the JSON binary format. Actually, we… 

DBA, turkeys and NoSQL hype

By Franck Pachot . We (DBAs) look at this NoSQL hype with a large smile. We know how powerful are SQL databases and we can’t imagine processing data seriously without it. And the technologies that come with NoSQL brings back the problem that we have solved with SQL databases. But can’t we ignore what is currently going on. Behind the…