Skip to content

Open source Team

Posts published under the Open source Team account are collective contributions by the dbi services open infrastructure consultants. The practice covers open-source databases and platforms, PostgreSQL first of all, along with MySQL, MariaDB, and Linux, from architecture, replication, and high availability to performance tuning and operations under service level agreements, and contributes actively to the PostgreSQL community.

721 posts since September 2011

8000 databases in one PostgreSQL cluster?

A while ago I posted this tweet on Twitter: #Postgresql friends: 8000 databases. One cluster, 8000 clusters, Kubernetes,, what would be your choice? Let's assume 10gb per database. I know backup/restore, inodes etc, no discussions about that, just thoughts and ideas — Daniel Westermann (@westermanndanie) January 27, 2021 While this might sound unusual, this actually was under consideration by one… 
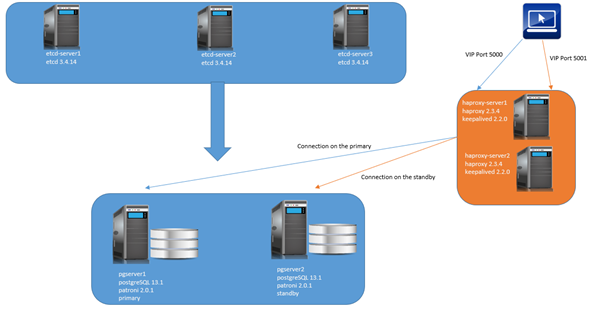
PostgreSQL High Availability: Patroni, Ectd , HAProxy , Keepalived

By Mouhamadou Diaw Patroni is one the most famous tool that can be used to setup a high avalaibilty for PostgreSQL. In this blog I am describing a test I did. Below the environment we will use The etcd cluster will contains 3 servers etcd-server1: 192.168.56.100 etcd-server2: 192.168.56.101 etcd-server3: 192.168.56.106 HAProxy and Keepalived will be configured in this 2 servers.… 

An introduction into server side programming in PostgreSQL – 1 – SQL functions, basics

Over the last years I’ve seen many different applications running against PostgreSQL. The use cases vary from simple applications, which only use basic data types and a few tables and views, to complex applications with custom types, more specific data types like jsonb or range types, that use hundreds of schemas/tables/views/materialized views etc. Surprisingly only a few of them make… 

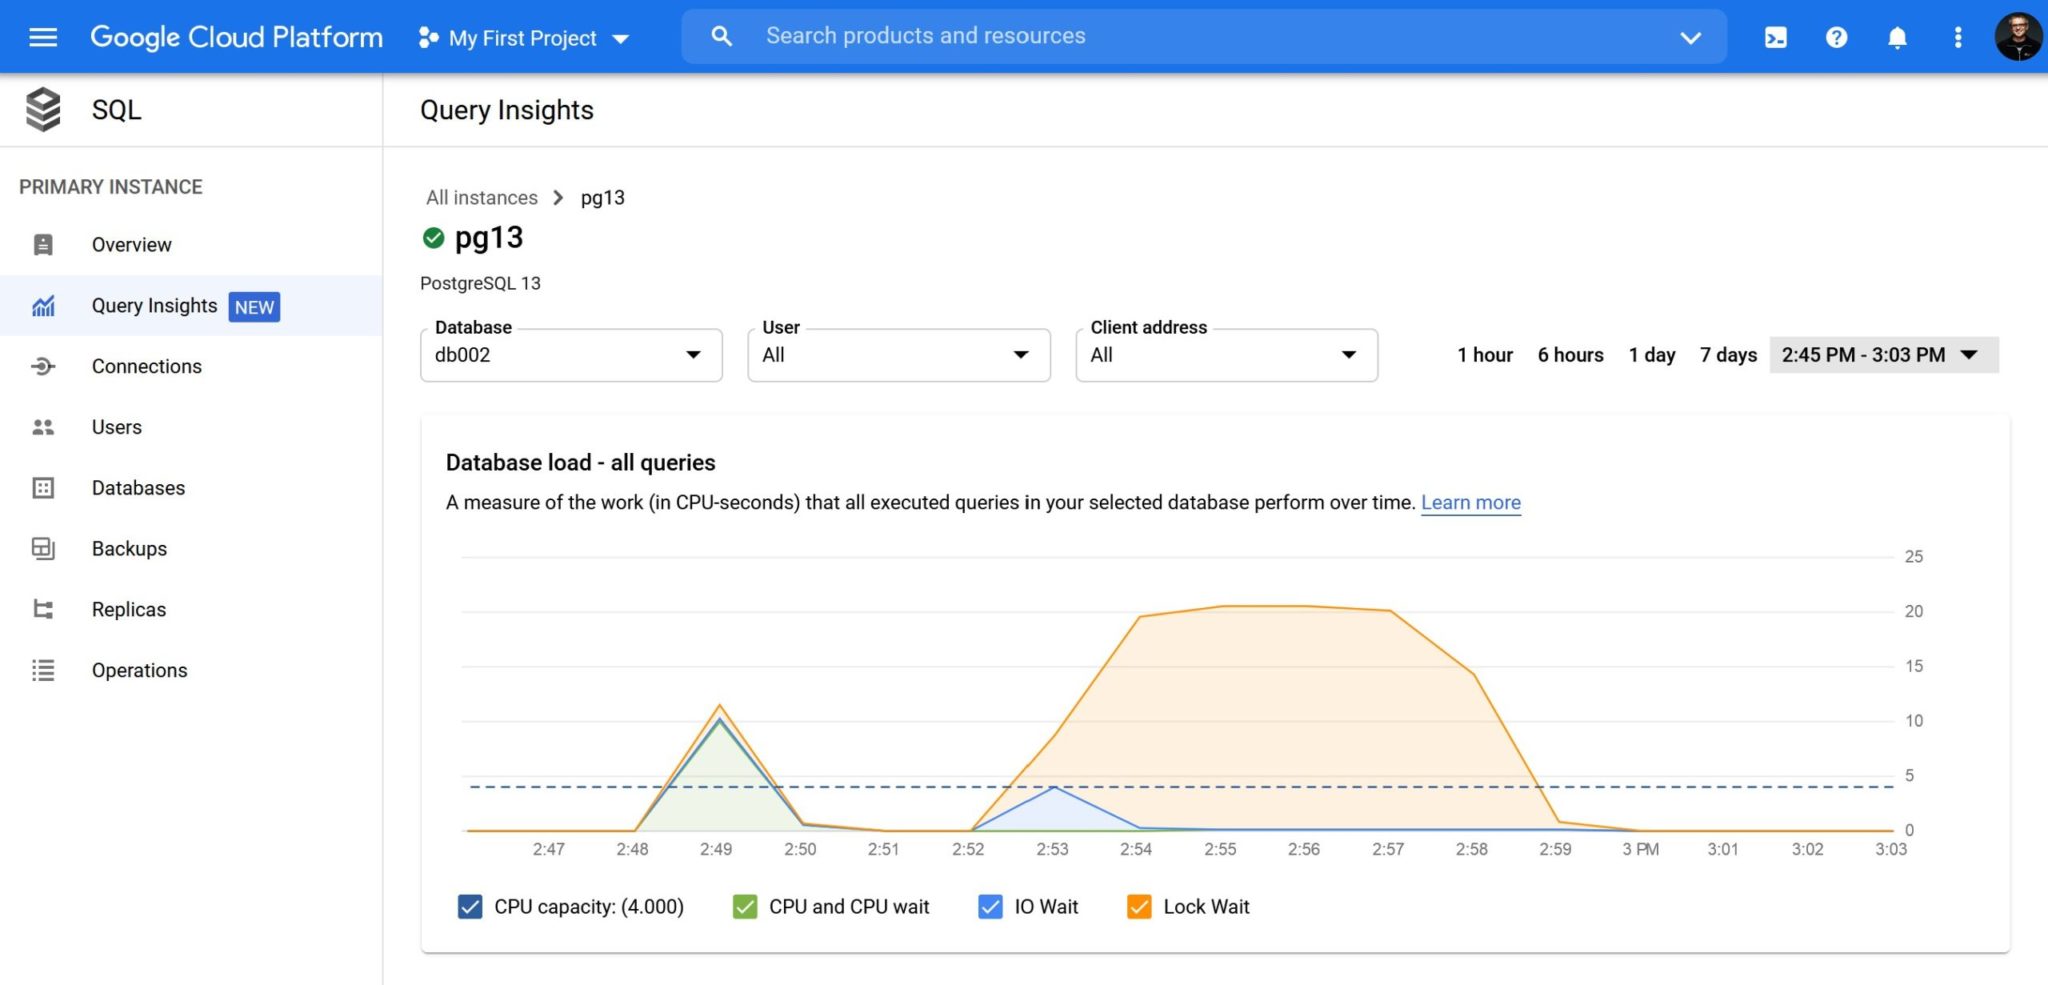
Google Cloud SQL Insights: ASH, plans and statement tagging

By Franck Pachot . Looking at database performance has always been necessary to optimize the response time or throughput, but when it comes to public cloud where you are charged by resource usage, performance tuning is critical for cost optimization. When looking at host metrics, you see only the symptoms and blindly guess at some solutions: add more vCPU if… 

Dealing with German “Umlaute” in PostgreSQL’s full text search

PostgreSQL comes with build-in Full Text Search and you can do quite amazing stuff with it. A question that popped up during one of the last PostgreSQL for developers workshop was: How can I deal with German “Umlaute” such as “ä”, “ö” and “ü” in such a way, that I can search for e.g. “Schnösel” and the result will give… 

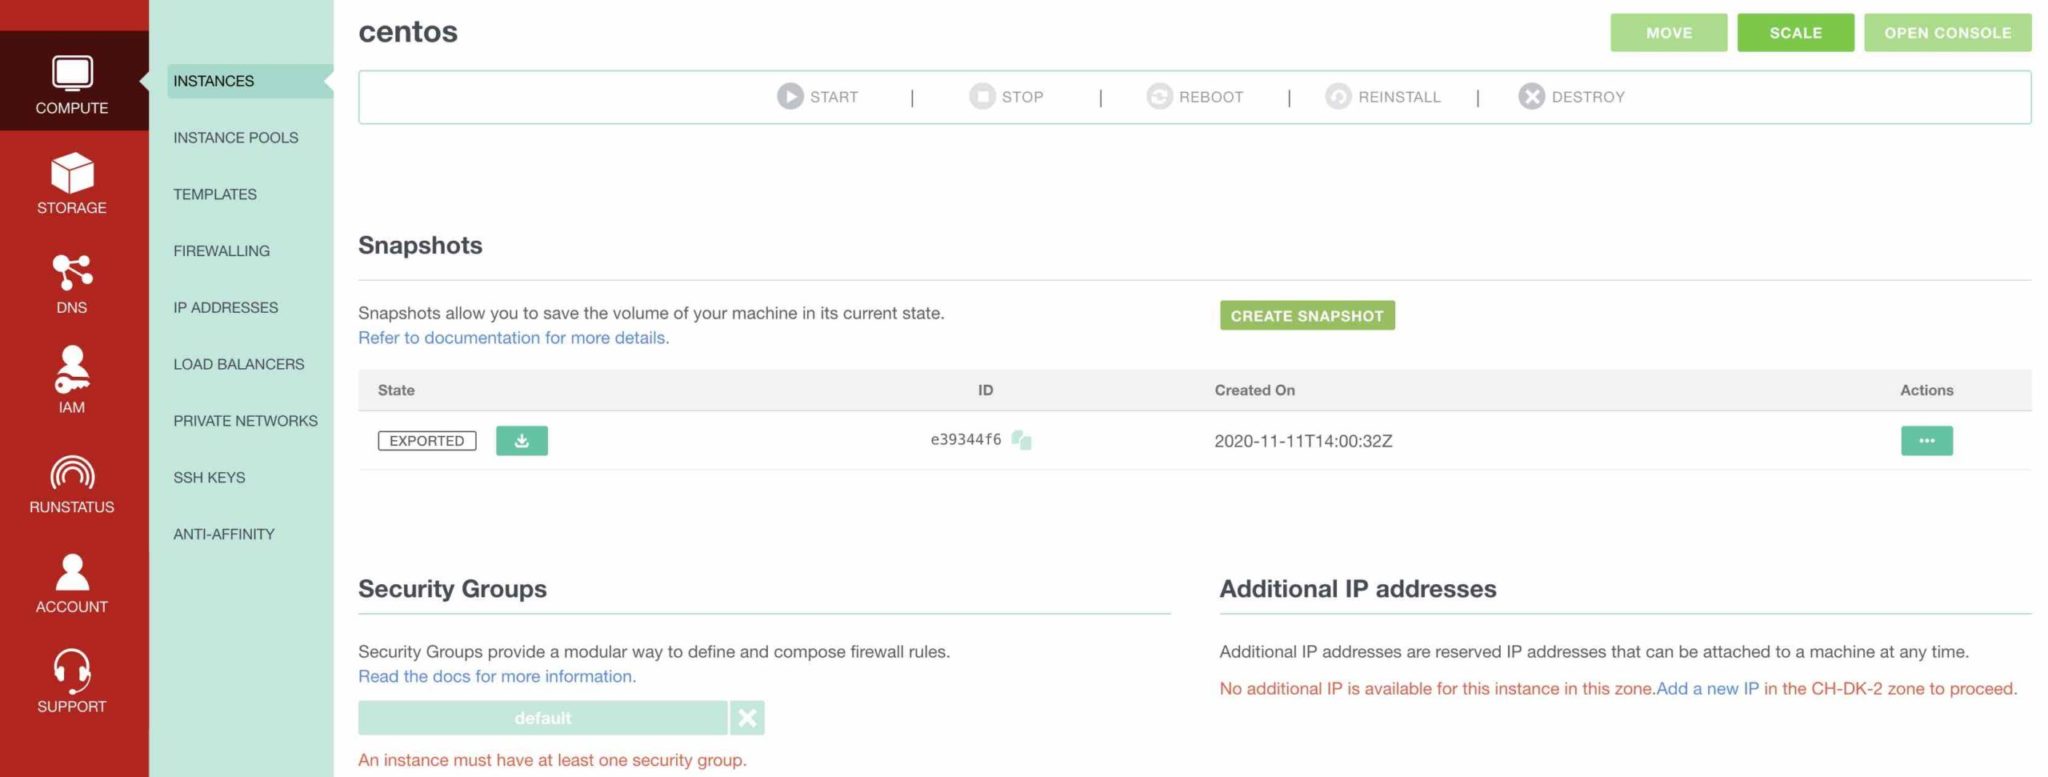
Exoscale scaling up and down

In my previous Blog I had wrote about Swiss Cloud Provider: Exoscale. Read the Blog Today we will look little bit deeper in three subjects: Template & Template sharing Scaling up and down instances dbi CentOS 8 & Debian 10 Templates Templating On Exoscale you can create custom Template from you current Instance. Custom Templates can make your daily work… 

Cluster level encryption for PostgreSQL 14

The discussions how and why TDE (Transparent data encryption) should be implemented in PostgreSQL goes back several years. You can have a look at these two more recent threads to get an idea on how much discussion happened around that feature: [Proposal] Table-level Transparent Data Encryption (TDE) and Key Management Service (KMS) Re: Internal key management system Finally an essentials… 

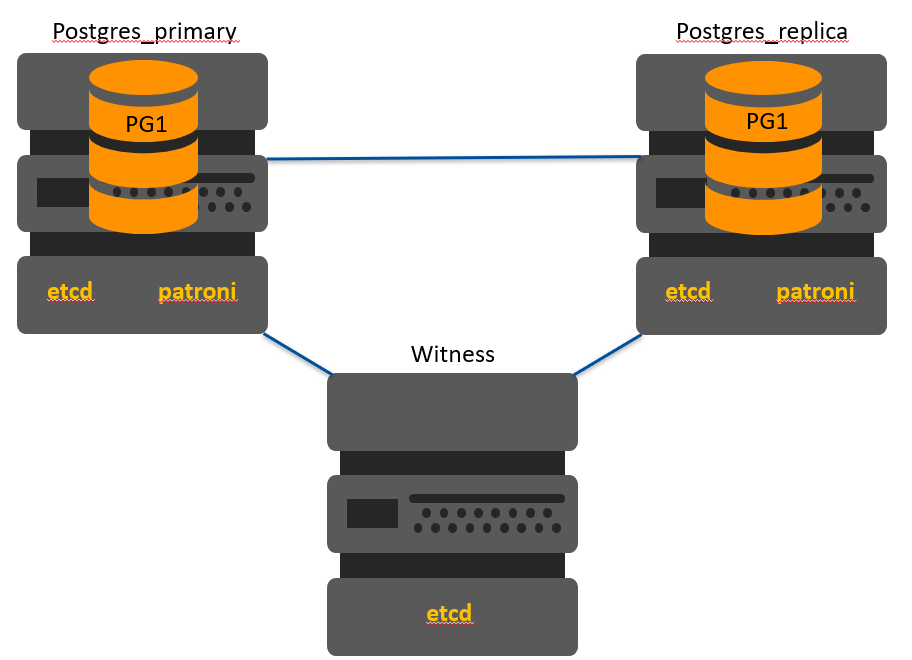
Running two Patroni on one host using an existing etcd

Have you ever asked yourself, how to create a second Patroni PostgreSQL cluster on an existing server using the existing etcd? My first idea was to study the documentation of Patroni, but unfortunately without big success. This post should help to identify the changes you have to do on the hosts to run two parallel Patroni clusters using an existing… 

DynamoDB Scan: the most efficient operation 😉

By Franck Pachot . The title is provocative on purpose because you can read in many places that you should avoid scans, and that Scan operations are less efficient than other operations in DynamoDB. I think that there is a risk, reading those message without understanding what is behind, that people will actually avoid Scans and replace them by something… 

pg_auto_failover: Failover and switchover scenarios

In the last post we had a look at the installation and setup of pg_auto_failover. We currently have one primary cluster and two replicas synchronizing from this primary cluster. But we potentially also have an issue in the setup: The monitor is running beside the primary instance on the same node and if that nodes goes down the monitor is…