Skip to content

pgvector

pgvector, a guide for DBA – Part 2: Indexes (update march 2026)

Introduction In Part 1 of this series, we covered what pgvector is, how embeddings work, and how to store them in PostgreSQL. We ended with a working similarity search — but on a sequential scan. That works fine for a demo table with 1,000 rows. It does not work for production. This post is about what comes next: indexes. Specifically,… 
RAG Series – Embedding Versioning LAB

Introduction This is Part 2 of the embedding versionin, in Part 1, I covered the theory: why event-driven embedding refresh matters, the three levels of architecture (triggers, logical replication, Flink CDC), and how to detect and skip insignificant changes. If you haven’t read it, go there first, this post won’t through the entire intent of the designs but just demonstrate… 

RAG Series – Embedding Versioning with pgvector: Why Event-Driven Architecture Is a Precondition to AI data workflows

Introduction “Make it simple.” This is a principle I keep repeating, and I’ll repeat it again here. Because when it comes to keeping your RAG system’s embeddings fresh, the industry has somehow made it complicated. External orchestrators, custom Python cron jobs, microservices that call microservices, Airflow DAGs with 47 tasks, all to answer a simple question: when my source data… 

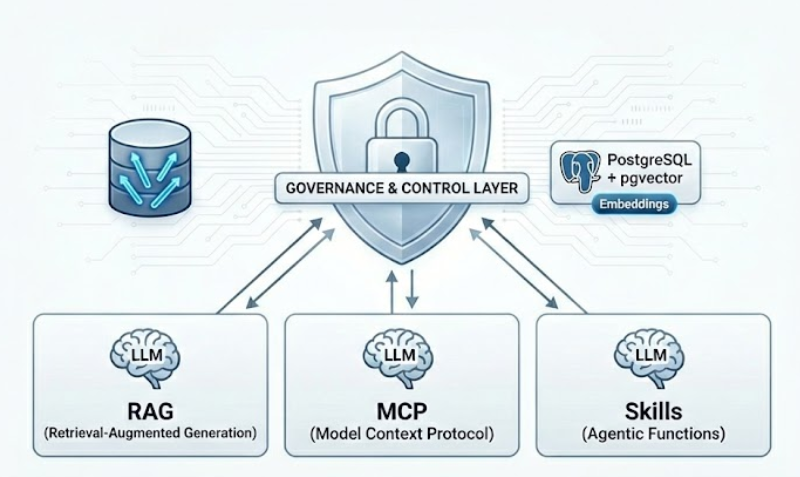
RAG, MCP, Skills — Three Paradigms for LLMs Talking to Your Database, and Why Governance Changes Everything

Introduction Throughout my RAG series, I’ve explored how to build retrieval-augmented generation systems with PostgreSQL and pgvector — from Naive RAG through Hybrid Search, Adaptive RAG, Agentic RAG, and Embedding Versioning (not yet released) . The focus has always been on retrieval quality: precision, recall, nDCG, confidence. But I want to take a step back. In conversations with colleagues, clients,… 

RAG Series – Agentic RAG

Introduction In earlier parts, we moved from Naive RAG (vector search) to Hybrid RAG (dense + sparse) to Adaptive RAG (query classification and dynamic weighting). Each step improved what we retrieve. Agentic RAG goes further: the LLM decides if and when to retrieve at all and can take multiple steps (retrieve → inspect → refine → retrieve) before answering. Retrieval… 

RAG Series – Hybrid Search with Re-ranking

Introduction In the first part of this RAG series, we established the fundamentals of Naive RAG with dense vector embeddings on PostgreSQL using pgvector. That foundation works well for conceptual queries, but production systems quickly reveal a limitation: pure semantic search misses exact matches like you would have with like or Full-text searches. When someone searches for “PostgreSQL 17 performance… 

Technological debt with AI workflows: When data hits the fan?

AI projects are increasing and with it comes some risks that are or not related to this technology. Some organizations are jumping straight into “plug the LLM into a vector database” ( like Pinecone, Qdrant, pgvector…) at the risk of replaying the lift-and-shift mistakes made on the cloud projects. This time, hiding years of data-quality, governance, code, architectural debt behind… 

pgvector, a guide for DBA – Part1: LAB DEMO

Introduction The first release of pgvector occurred in April 2021. Since then a lot has changed and is still changing. Even though we could say that the level of maturity of AI stacks and usage is currently really amazing, things are still changing fast and will probably continue to do so for a while. This is quite exciting because as…