Skip to content

Columnstore

Stored procedure execution may fail with nonclustered columnstore indexes

In this blog post, let’s talk about a weird situation where I faced a nonclustered columnstore issue with SQL Server 2012. Let’s say we are in the same context than this previous blog post here. So as a reminder, we decided to benefit from the columnstore index feature after installing a new SQL Server 2012 based infrastructure at my customer… 
Columnstore index rebuild cannot start

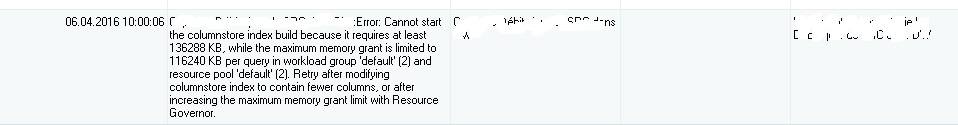
A couple of weeks ago, I was charged to migrate an SQL Server datawarehouse environment to a more recent version of SQL Server (from 2005 to 2012 in my case). After discussing with my customer we decided to benefit from the nonclustered columnstore index feature to improve reporting queries performance directly executed against the concerned database. So the implementation was… 

SQL Server 2016 : nonclustered columnstore index and aggregate pushdown

Did you miss aggregate pushdown capability shipped with columnstore index? Well, I remember the first time I heard about it is was when I read the very interesting blog post of Niko Neugebauer here with a very good covering of the topic (principle, advantages and limitations). So why to write a new blog post here? Well because since the last… 

Clustered columnstore index and memory management

Few weeks ago, I had the opportunity to give a session about the clustered columnstore index feature (CCI) at our In-Memory event dedicated to In-Memory technologies for Microsoft SQL Server, Oracle and SAP HANA. During our session, I explained the improvement made by Microsoft on SQL Server 2014 with the introduction of new clustered columnstore index (CCI). The CCI includes… 

SQL Server 2016 : availability groups and the new clustered columnstore index support

This blog post is focused on the new supportability of clustered columnstore index on the high- availability read-only replicas. Others studies are available here: New database issue level detection for automatic failover Potential features in standard edition Automatic failover enhancements New load balancing features with read-only replicas After reading some improvements from the columnstore index feature side, I was very… 

SAP HANA SQL scripting optimization: the CE Functions

In SAP HANA, you have two possibilities to create the Calculated Views: Using the graphical method Using the scripting method with CE functions In this blog, I will demonstrate that CE Functions can improve performances from a Calculated View. First, I will give you some general information regarding the CE Functions. After that, I will show you the two different… 

What that in-memory term is about, and what not

Everybody is talking about in-memory databases these days. And everybody is talking about columnar store for sets of data because this can be a benefit for analytic queries. And a lot of people start mixing these terms not realizing that these topics are not exchangeable. Traditionally in-memory means: Not persistent, but fast. And this is what pure in-memory databases are:… 

Row Store vs Column Store in SAP HANA

The SAP HANA database allows you to create your tables in Row or Column Store mode. In this blog, I will demonstrate that each method has its advantages and disadvantages and should be used for specific cases. Thanks to two kind of tests, I will show you that the Row Store mode should be used for simple SELECT SQL queries,… 

Optimized Row Columnar (ORC) format in PostgreSQL

Nowadays everybody is talking about columnar storage format. What can PostgreSQL do in this area? There is no native support for that in PostgreSQL but thanks to the fact that PostgreSQL is highly extensible there is a foreign data wrapper called cstore_fdw. Lets take a look on what it can do. For installing cstore_fdw we’ll need to install the protobuf-c-devel package…